Introduction
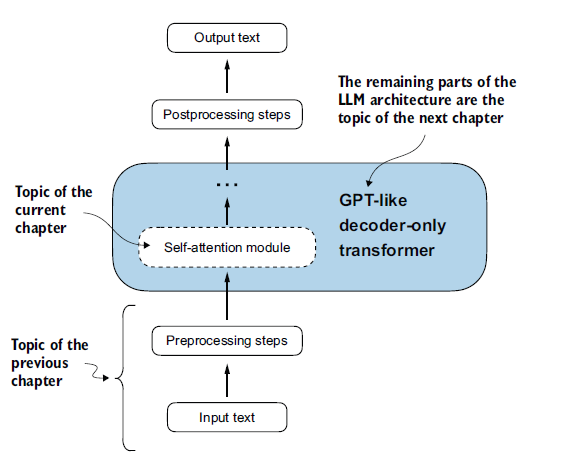
This chapter covers attention mechanisms, which are the core of the LLM architecture. The goal is to understand how they work, in isolation and mechanically, before integrating them into the full model in chapter 4.
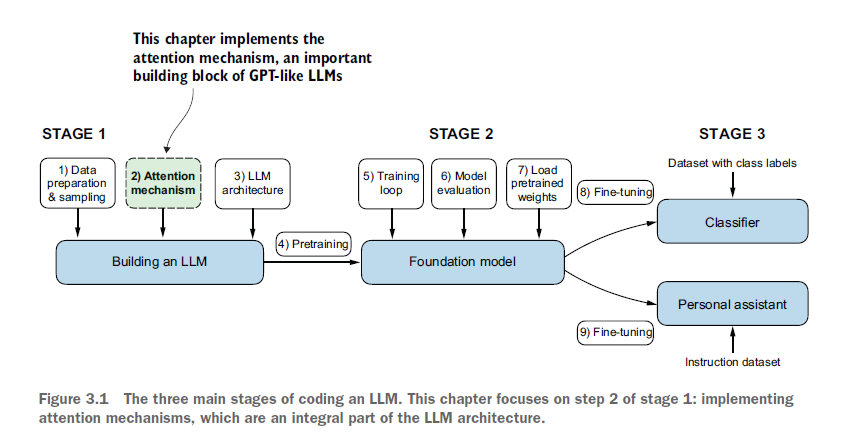
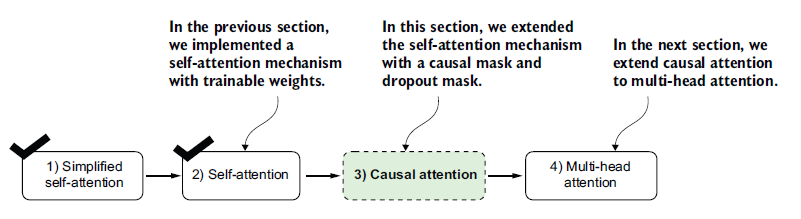
Four variants of the attention mechanism will be implemented step by step, each building on the previous one:
- Simplified self-attention: a stripped-down version, with no trainable weights, to grasp the fundamental logic.
- Self-attention with trainable weights: the complete, trainable version.
- Causal attention: a mask is added so that the model cannot “see” future tokens while generating text token by token.
- Multi-head attention: several attention mechanisms run in parallel, letting the model capture different aspects of the relationships between tokens at the same time.
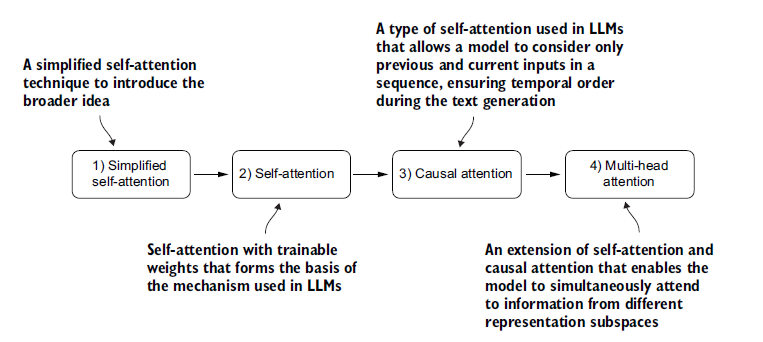
The final multi-head attention implementation will be reused as is in the LLM architecture in the next chapter.
The Problem with Modeling Long Sequences
Before introducing the self-attention mechanism, it helps to understand the problem it solves, and why the architectures that came before it fell short.
The context: machine translation
Take a translation model. Translating word by word is impossible: the grammatical structures of the source and target languages differ too deeply.
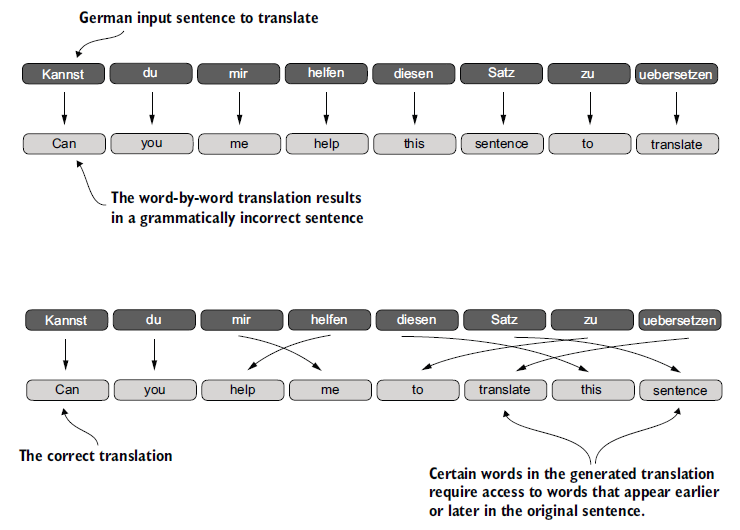
The classic solution is an encoder-decoder architecture: the encoder reads and compresses the input sequence, and the decoder produces the translated sequence from that compressed representation.
The encoder-decoder architecture with RNNs
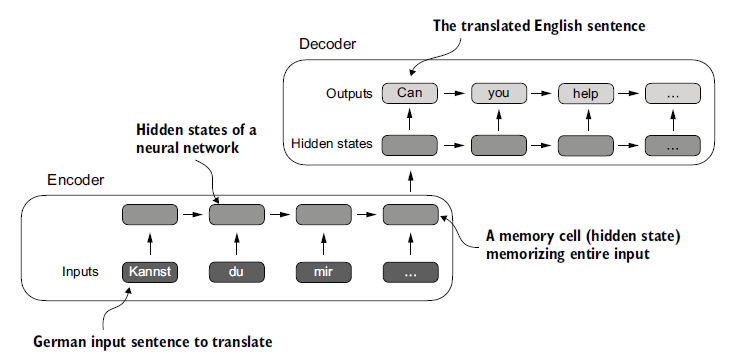
Before Transformers, recurrent neural networks (RNNs) dominated this task. An RNN processes the sequence token by token, maintaining a hidden state that is updated at each step: a kind of internal memory carried along the sequence.
In an encoder-decoder RNN:
- The encoder goes through the entire input sequence and tries to condense its meaning into a single final hidden state vector.
- The decoder takes this vector as its starting point and generates the translation token by token, maintaining its own hidden state at each step.
The fundamental limitation
This final hidden state vector is the bottleneck of the architecture. All the information in the input sequence (however long it is) has to fit into this single vector. During decoding, the model no longer has access to the encoder’s intermediate hidden states: all it has is this compressed representation.
On short sentences, this works. On long sequences with distant dependencies, the context gets diluted and lost: this is long-range context loss.
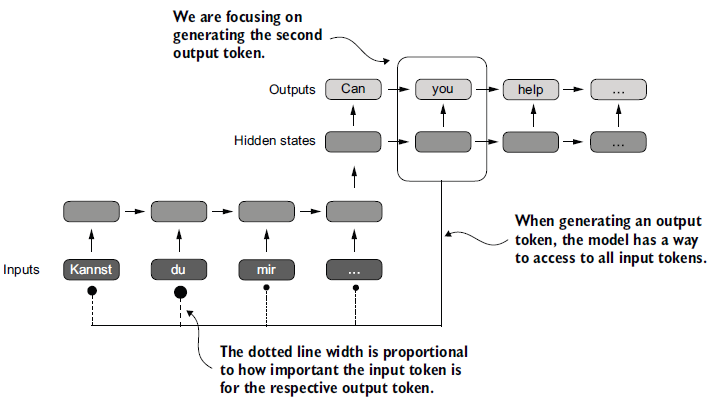
This is exactly the limitation that motivated the invention of attention mechanisms: rather than forcing all the information into a single vector, let the decoder directly access all of the encoder’s hidden states, weighting their relevance according to the token being generated.
Capturing Dependencies with Attention Mechanisms
Bahdanau attention (2014), the first breakthrough
To get around the bottleneck of the single hidden vector, Bahdanau et al. proposed in 2014 a modification of the encoder-decoder RNN: instead of passing on only the final hidden state, all of the encoder’s intermediate hidden states remain accessible. At each decoding step, the decoder computes a relevance score for each of them and weights what it reads accordingly: these are called attention weights.
The Transformer (2017), the second breakthrough
Three years later came a more radical discovery: the RNN itself is not needed. The Transformer architecture, proposed in 2017, keeps the principle of attention weights but drops recurrence entirely. It introduces self-attention: a mechanism through which each token in a sequence can directly weigh the relevance of every other token in the same sequence, without going through intermediate hidden states.
Self-attention in one sentence
To compute its representation, each token looks at the whole sequence and decides, through learned weights, which other tokens it should “pay attention” to.
This mechanism is at the heart of modern LLMs such as GPT, and it is what this chapter implements from scratch.
Self-Attention: Attending to Different Parts of the Input
The “self” in self-attention
The word self refers to the fact that the mechanism operates within one and the same sequence: each token computes its attention weights by comparing itself with all the other tokens of the same sequence. This is what sets it apart from classic Bahdanau attention, where the weights are computed between two different sequences (input and output).
Simplified Self-Attention, Without Trainable Weights
Before introducing trainable weights, we implement a stripped-down version to grasp the fundamental logic. The goal is to compute, for each input token , a context vector , that is, an enriched version of its embedding that incorporates information from all the other tokens in the sequence.
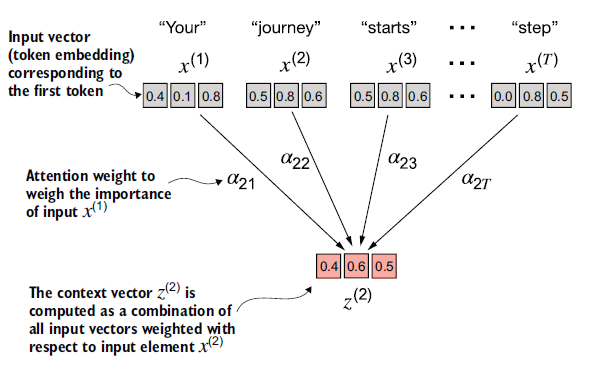
We work on the sentence “Your journey starts with one step.”, already encoded as 3-dimensional vectors:
import torch

inputs = torch.tensor(
    [[0.43, 0.15, 0.89],  # Your     (x^1)
     [0.55, 0.87, 0.66],  # journey  (x^2)
     [0.57, 0.85, 0.64],  # starts   (x^3)
     [0.22, 0.58, 0.33],  # with     (x^4)
     [0.77, 0.25, 0.10],  # one      (x^5)
     [0.05, 0.80, 0.55]]  # step     (x^6)
)
Computing the context vector takes three steps.
Step 1. Compute the attention scores (dot product)
For the query token (“journey”), we compute its dot product with each token of the sequence. This score measures similarity: the higher it is, the more aligned the two tokens are in the vector space, and the more one should “pay attention” to the other.
query = inputs[1]  # x^(2): "journey"

attn_scores_2 = torch.empty(inputs.shape[0])
for i, x_i in enumerate(inputs):
    attn_scores_2[i] = torch.dot(x_i, query)

print(attn_scores_2)
tensor([0.9544, 1.4950, 1.4754, 0.8434, 0.7070, 1.0865])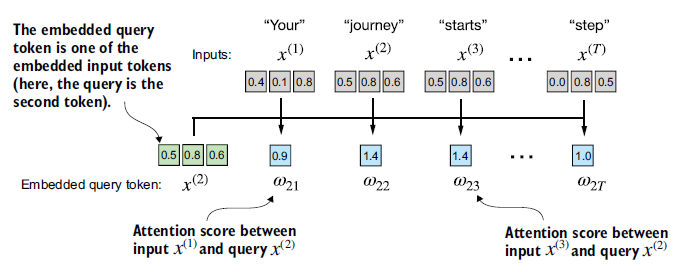
Dot product. It multiplies two vectors element by element and sums the results. Writing the explicit loop is equivalent to using
torch.dot:res = 0. for idx, element in enumerate(inputs[0]): res += inputs[0][idx] * query[idx] print(res) # tensor(0.9544) print(torch.dot(inputs[0], query)) # tensor(0.9544)
Step 2. Normalize to get the attention weights (softmax)
We normalize the scores to get attention weights that sum to 1, which makes them interpretable as relative importances.
A naive normalization by the sum does produce valid weights:
attn_weights_2_tmp = attn_scores_2 / attn_scores_2.sum()
print("Attention weights:", attn_weights_2_tmp)
print("Sum:", attn_weights_2_tmp.sum())
Attention weights: tensor([0.1455, 0.2278, 0.2249, 0.1285, 0.1077, 0.1656])
Sum: tensor(1.0000)In practice, softmax is always preferred, for two deep reasons.
Why softmax rather than simple normalization?
Reason 1. Numerical stability. The naive softmax computes:
In float32, gives inf as soon as (overflow) and rounds to zero as soon as
(underflow). On long sequences, attention scores can
easily cross these thresholds:
torch.exp(torch.tensor(89.0))    # → tensor(inf): overflow
torch.exp(torch.tensor(-104.0))  # → tensor(0.): underflow
We then get inf/inf = NaN or 0/0 = NaN, and the gradient becomes unusable.
PyTorch gets around this with the log-sum-exp trick: subtract the maximum score
before exponentiating,
which is mathematically identical (the cancels out between numerator and denominator) but numerically stable: the largest value becomes , and all the others fall within .
Reason 2. Favorable gradient properties. Let’s compare the Jacobians of the two normalizations.
Simple normalization , :
The gradient depends on , the raw sum of the scores: if is large, the gradient collapses and the update signal propagates poorly. Moreover, this formula requires positive scores, which the dot product does not guarantee.
Softmax , :
Deriving the Jacobian. We apply the quotient rule to .
Case :
Case : , but , so:
Both cases combine using the Kronecker delta :
This Jacobian has three concrete advantages:
- Gradient independent of the raw scale: it only depends on . The signal stays within a controlled range whatever the magnitude of the scores.
- Strictly nonzero gradient: since strictly, . The correction signal never silently dies out.
- Amplified differences: the exponential accentuates the gaps between scores. A small advantage in score produces a more pronounced advantage in weight, giving sharper attention patterns and more informative gradients.
Implementation
# Naive version: unstable on large values
def softmax_naive(x):
    return torch.exp(x) / torch.exp(x).sum(dim=0)

# PyTorch version: built-in log-sum-exp, use this in practice
attn_weights_2 = torch.softmax(attn_scores_2, dim=0)
print("Attention weights:", attn_weights_2)
print("Sum:", attn_weights_2.sum())
Attention weights: tensor([0.1385, 0.2379, 0.2333, 0.1240, 0.1082, 0.1581])
Sum: tensor(1.)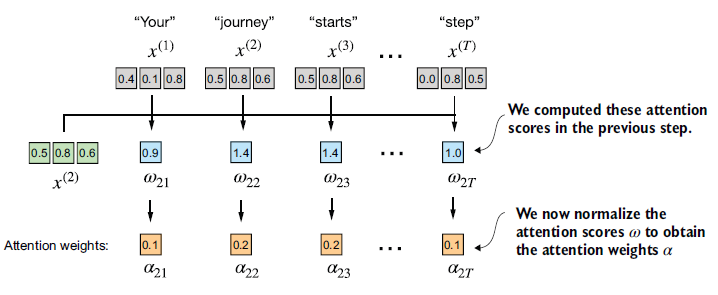
Step 3. Compute the context vector (weighted sum)
The context vector is the weighted sum of all the input vectors, each multiplied by its attention weight:
context_vec_2 = torch.zeros(query.shape)
for i, x_i in enumerate(inputs):
    context_vec_2 += attn_weights_2[i] * x_i

print(context_vec_2)
tensor([0.4419, 0.6515, 0.5683])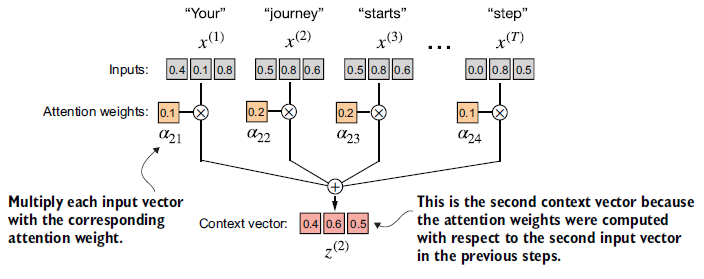
Unlike the raw embedding of “journey” [0.55, 0.87, 0.66], the context
vector [0.4419, 0.6515, 0.5683] encodes not only the meaning of “journey”,
but also its weighted relationship with every other token in the sentence.
The next step is to generalize this computation to produce all the context vectors to at once.
Generalization: Attention Weights for All Tokens
We apply the same pipeline to all tokens at once, replacing the loops with matrix operations.
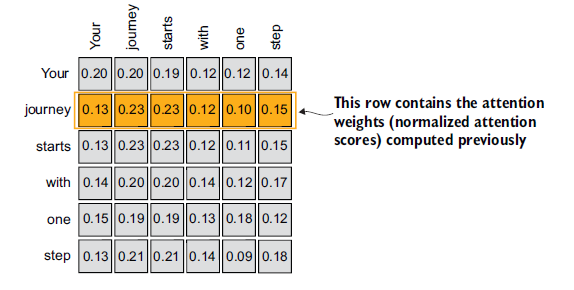
Step 1. Attention scores for all pairs
attn_scores = inputs @ inputs.T
print(attn_scores)
tensor([[0.9995, 0.9544, 0.9422, 0.4753, 0.4576, 0.6310],
[0.9544, 1.4950, 1.4754, 0.8434, 0.7070, 1.0865],
...])Why
inputs @ inputs.Tis equivalent to the double loop.inputsis a matrix of shape(6, 3): 6 tokens, each represented by a 3-dimensional vector.inputs.Tis its transpose, of shape(3, 6). Their matrix product gives a(6, 6)tensor whose element equals , which is exactly the dot product between tokens and , what the double loop computed explicitly.
Step 2. Normalization with softmax
attn_weights = torch.softmax(attn_scores, dim=-1)
dim=-1tells PyTorch to apply softmax along the last dimension, here the columns. Each row is normalized independently, so that its values sum to 1.
Step 3. Context vectors
all_context_vecs = attn_weights @ inputs
print(all_context_vecs)
tensor([[0.4421, 0.5931, 0.5790],
[0.4419, 0.6515, 0.5683],
[0.4431, 0.6496, 0.5671],
[0.4304, 0.6298, 0.5510],
[0.4671, 0.5910, 0.5266],
[0.4177, 0.6503, 0.5645]])attn_weights is (6, 6) and inputs is (6, 3): the product is (6, 3), where each row is the sum of all the input vectors weighted by token ‘s attention weights.
This version still has no trainable parameters. The next section introduces the matrices , , to make the mechanism truly trainable.
Implementing Self-Attention with Trainable Weights
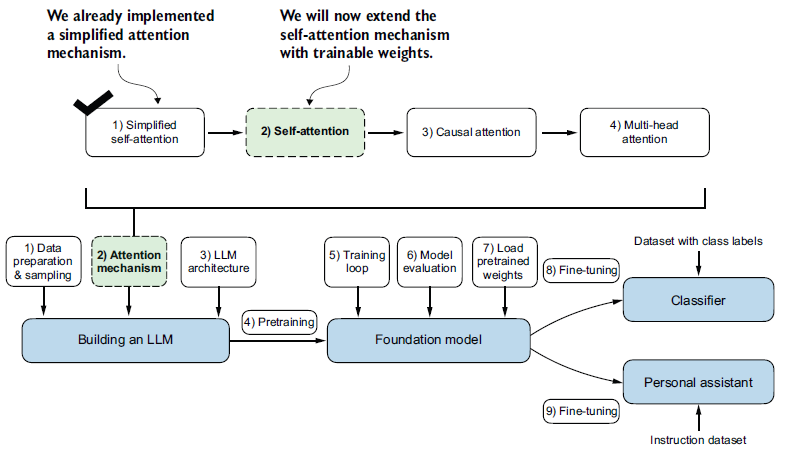
The structural difference from the simplified version is the introduction of three trainable weight matrices , , , updated through backpropagation. They are what give the model the ability to learn which kind of similarity matters for the task, rather than measuring raw similarity between embeddings.
Computing the Attention Weights Step by Step
The three projection matrices and their roles
Each input token is projected into three distinct subspaces through these matrices:
The terms query, key and value come from databases and information retrieval:
-
Query : the request issued by token to question all the other tokens: it lets token find, among them, the ones that matter for building its contextual representation.
-
Key : the index key of token : each token exposes a key that is compared with the other tokens’ queries to determine its relevance.
-
Value : the actual information content of token , like the value in a key-value pair of a dictionary: it is what actually gets passed on if the token is judged relevant.
The mechanism then works in three steps: compare the query with all the keys through the dot product , identify the most relevant tokens through softmax, then retrieve the corresponding values weighted by these scores to form the context vector .
It is a bit like a search engine: you type “best pizzerias in Paris” (query), Google compares it with the titles and metadata of every indexed page (keys), then returns the actual content of the most relevant pages (values).
In the simplified version seen earlier, : there was no learned projection, and the similarity measured was the raw closeness between embeddings. Introducing , , lets the model learn specialized representations for each of these three roles.
Matrix weights vs. attention weights. The entries of , , are learned parameters, that is, scalars optimized by gradient descent and fixed once training is over. The attention weights , on the other hand, are dynamic: recomputed on every forward pass from the current input. These are two different uses of the word “weight”.
Implementation
x_2 = inputs[1]          # token "journey", shape: (3,)
d_in  = inputs.shape[1]  # 3
d_out = 2                 # output dimension (in GPT, d_in == d_out)

torch.manual_seed(123)
W_query = torch.nn.Parameter(torch.rand(d_in, d_out), requires_grad=False)
W_key   = torch.nn.Parameter(torch.rand(d_in, d_out), requires_grad=False)
W_value = torch.nn.Parameter(torch.rand(d_in, d_out), requires_grad=False)
requires_grad=False turns off gradient computation for these matrices here, only to keep the printed output short. In real training, we would set requires_grad=True so that they get updated through backpropagation.
We project and all the tokens:
query_2 = x_2 @ W_query   # shape: (2,)
keys    = inputs @ W_key   # shape: (6, 2)
values  = inputs @ W_value # shape: (6, 2)

print(query_2)
tensor([0.4306, 1.4551])We have projected the 6 three-dimensional tokens into a two-dimensional space. We only compute query_2 for the current token, but we need the keys and values of all the tokens to weight their contribution to the context vector of .
Step 1. Attention scores
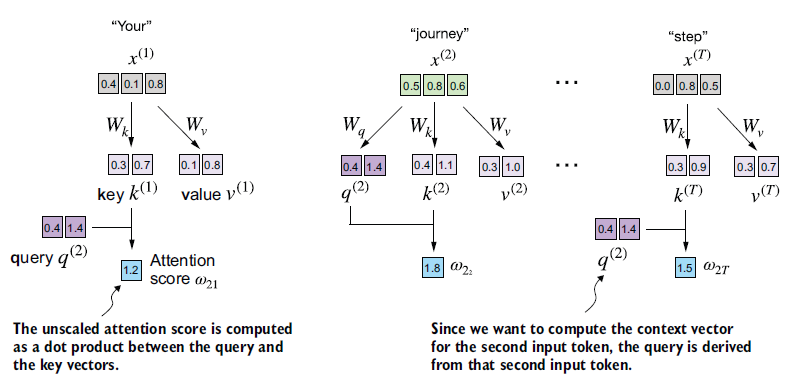
attn_scores_2 = query_2 @ keys.T
print(attn_scores_2)
tensor([1.2705, 1.8524, 1.8111, 1.0795, 0.5577, 1.5440])Step 2. From scores to attention weights: the 1/√dₖ factor
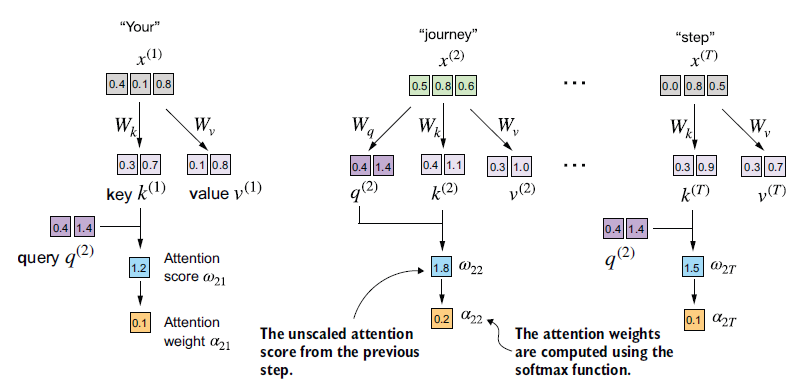
d_k = keys.shape[-1]  # dimension of the keys = 2
attn_weights_2 = torch.softmax(attn_scores_2 / d_k**0.5, dim=-1)
print(attn_weights_2)
tensor([0.1500, 0.2264, 0.2199, 0.1311, 0.0906, 0.1820])Why divide by ?
This is the justification that gives the architecture its name: scaled dot-product attention.
Assume the components of and are approximately i.i.d. with distribution . The dot product is then a sum of independent random variables with mean 0 and variance 1, so:
Proof
Let and , independent.
Step 1. Variance of the product
Since are independent, their squares follow independent chi-squared distributions with 1 degree of freedom:
For a distribution: . By independence of and :
And , so:
Step 2. Variance of the sum
The terms are independent of each other (the indices are distinct), so the variance of their sum is the sum of their variances:
Step 3. Standard deviation
Step 4. After scaling by
The variance is brought back to 1 whatever the value of .
For (typical in GPT), the dot products have a standard deviation of about 32. Softmax therefore receives very spread-out inputs: large values push toward 1, small ones toward 0, and the distribution looks like a one-hot vector.
But the gradient of softmax is : when or , this gradient tends to 0. We are back to the vanishing gradient problem: training stalls.
Dividing by brings the variance of the score back to 1:
The softmax inputs stay within reasonable ranges whatever is: the attention weights no longer collapse toward 0 or 1, and the gradients remain usable.
Step 3. Context vector
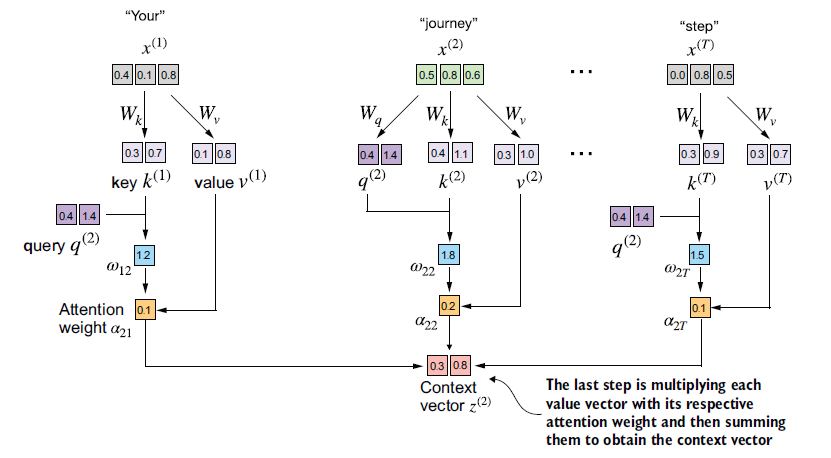
context_vec_2 = attn_weights_2 @ values
print(context_vec_2)
tensor([0.3061, 0.8210])The fundamental difference from the simplified version: we sum the value vectors , not the raw embeddings . lets the model learn which information to extract from each token and pass on, independently of how that token is indexed (key) or how it queries the others (query).
Explicitly, the context vector of is:
In compact matrix form, for all the tokens at once:
where , , are the projections of the whole sequence, and each row of is the context vector .
Implementing a Compact Self-Attention Python Class
The previous code is reorganized into an nn.Module class, the building block of every PyTorch model, which automatically handles registering the parameters, updating them during training, and moving them to the GPU.
import torch.nn as nn

class SelfAttention_v1(nn.Module):
    def __init__(self, d_in, d_out):
        super().__init__()
        self.W_query = nn.Parameter(torch.rand(d_in, d_out))
        self.W_key   = nn.Parameter(torch.rand(d_in, d_out))
        self.W_value = nn.Parameter(torch.rand(d_in, d_out))

    def forward(self, x):
        keys    = x @ self.W_key
        queries = x @ self.W_query
        values  = x @ self.W_value
        attn_scores  = queries @ keys.T
        attn_weights = torch.softmax(attn_scores / keys.shape[-1]**0.5, dim=-1)
        context_vec  = attn_weights @ values
return context_vectorch.manual_seed(123)
sa_v1 = SelfAttention_v1(d_in, d_out)
print(sa_v1(inputs))tensor([[0.2996, 0.8053],
[0.3061, 0.8210],
[0.3058, 0.8203],
[0.2948, 0.7939],
[0.2927, 0.7891],
[0.2990, 0.8040]], grad_fn=<MmBackward0>)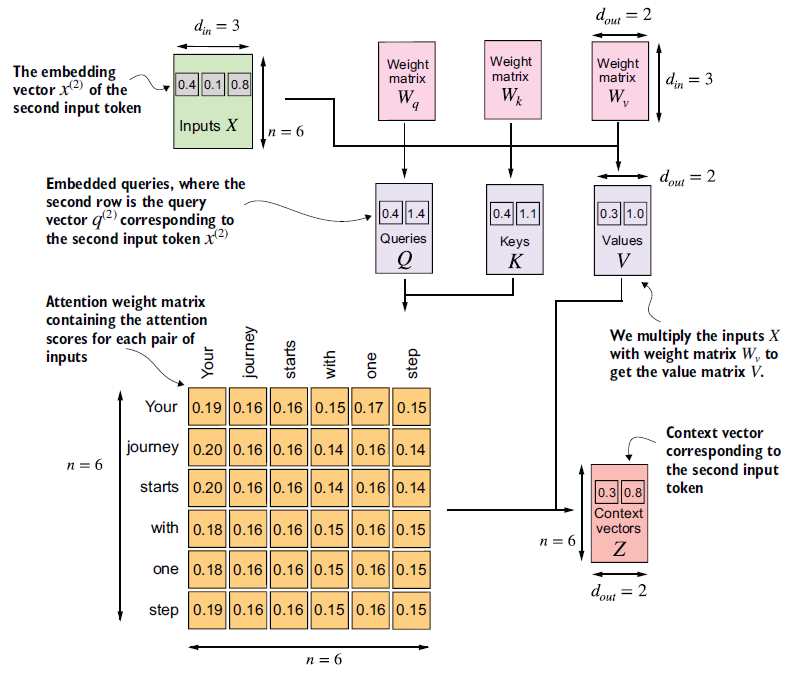
Improved version with nn.Linear
Weight initialization. In SelfAttention_v1, nn.Parameter(torch.rand(...)) draws each weight independently as . This initialization is naive for two reasons:
- The initial weights are all positive, which restricts the learning dynamics. A good initialization should instead differentiate the neurons effectively from the start by assigning random weights of varying signs (this is called symmetry breaking in the literature);
- the variance does not depend on , which makes the variance of the output explode when is large.
Proof
is the projection of the input embeddings into key space, with : each row is a token’s key vector, each column a dimension of key space. We look at the scalar:
the -th component of token ‘s key vector. It is the variance of this sum that we analyze to quantify the effect of the initialization.
Working assumptions. We assume and are independent, and (a standard assumption, satisfied after normalizing the inputs).
Variance of one term . With :
The key quantity is , which breaks down as:
Refresher: the uniform distribution .
Case torch.rand: .
The variance grows linearly with : for , it is 512 times larger than the input variance.
Kaiming case: .
The cancels out: the variance stays constant whatever the input dimension.
By default, nn.Linear uses Kaiming initialization (He, 2015), which sets:
which keeps the variance of the signal constant across layers, whatever the dimension.
nn.Linear as a linear operator. In SelfAttention_v1, we define as an nn.Parameter, and the forward pass computes:
nn.Linear(d_in, d_out, bias=False) internally stores a matrix , and calling it on computes:
The two expressions are identical if and only if , which is exactly how nn.Linear stores its weights. The two implementations are therefore strictly equivalent.
class SelfAttention_v2(nn.Module):
    def __init__(self, d_in, d_out, qkv_bias=False):
        super().__init__()
        self.W_query = nn.Linear(d_in, d_out, bias=qkv_bias)
        self.W_key   = nn.Linear(d_in, d_out, bias=qkv_bias)
        self.W_value = nn.Linear(d_in, d_out, bias=qkv_bias)

    def forward(self, x):
        keys    = self.W_key(x)
        queries = self.W_query(x)
        values  = self.W_value(x)
        attn_scores  = queries @ keys.T
        attn_weights = torch.softmax(attn_scores / keys.shape[-1]**0.5, dim=-1)
        context_vec  = attn_weights @ values
return context_vectorch.manual_seed(789)
sa_v2 = SelfAttention_v2(d_in, d_out)
print(sa_v2(inputs))tensor([[-0.0739, 0.0713],
[-0.0748, 0.0703],
[-0.0749, 0.0702],
[-0.0760, 0.0685],
[-0.0763, 0.0679],
[-0.0754, 0.0693]], grad_fn=<MmBackward0>)The outputs of v1 and v2 differ only because the initial weights are different; the logic of the forward pass is identical.
Exercise 3.1: Comparing SelfAttention_v1 and SelfAttention_v2
Transfer the weights of
SelfAttention_v2toSelfAttention_v1and check that both implementations produce the same outputs oninputs.
Solution:
nn.Linear stores its matrix as , so all we need is to transpose each weight before copying it.
sa_v1 = SelfAttention_v1(d_in, d_out)
sa_v1.W_query = torch.nn.Parameter(sa_v2.W_query.weight.T)
sa_v1.W_key   = torch.nn.Parameter(sa_v2.W_key.weight.T)
sa_v1.W_value = torch.nn.Parameter(sa_v2.W_value.weight.T)

print(torch.allclose(sa_v1(inputs), sa_v2(inputs)))TrueThe next step adds two extensions to this mechanism: the causal mask, which prevents each token from accessing future tokens during generation, and multi-head attention, which runs several attention mechanisms in parallel to capture different kinds of relationships between tokens.
Hiding Future Words with Causal Attention
Causal attention (or masked attention) is a variant of self-attention that restricts each token to the tokens that come before it (and itself) in the sequence. This is the opposite of standard self-attention, which has the whole sequence available as input.
This constraint is fundamental for GPT-style LLMs: when predicting the next token, the model must not “see” future tokens; that would be information leakage.
Applying a Causal Attention Mask
There are two equivalent approaches to obtaining the masked attention weight matrix.
Naive approach: mask after softmax
Step 1. Compute the standard attention weights (softmax)
queries = sa_v2.W_query(inputs)
keys    = sa_v2.W_key(inputs)
attn_scores   = queries @ keys.T
attn_weights  = torch.softmax(attn_scores / keys.shape[-1]**0.5, dim=-1)
tensor([[0.1921, 0.1646, 0.1652, 0.1550, 0.1721, 0.1510],
[0.2041, 0.1659, 0.1662, 0.1496, 0.1665, 0.1477],
[0.2036, 0.1659, 0.1662, 0.1498, 0.1664, 0.1480],
[0.1869, 0.1667, 0.1668, 0.1571, 0.1661, 0.1564],
[0.1830, 0.1669, 0.1670, 0.1588, 0.1658, 0.1585],
[0.1935, 0.1663, 0.1666, 0.1542, 0.1666, 0.1529]],
grad_fn=<SoftmaxBackward0>)Step 2. Build the lower triangular mask
context_length = attn_scores.shape[0]
mask_simple    = torch.tril(torch.ones(context_length, context_length))
tensor([[1., 0., 0., 0., 0., 0.],
[1., 1., 0., 0., 0., 0.],
[1., 1., 1., 0., 0., 0.],
[1., 1., 1., 1., 0., 0.],
[1., 1., 1., 1., 1., 0.],
[1., 1., 1., 1., 1., 1.]])torch.tril keeps the diagonal and the lower triangle and zeroes out the upper triangle, that is, exactly the future positions to mask.
Step 3. Zeroing: multiply the weights by the mask
masked_simple = attn_weights * mask_simpletensor([[0.1921, 0.0000, 0.0000, 0.0000, 0.0000, 0.0000],
[0.2041, 0.1659, 0.0000, 0.0000, 0.0000, 0.0000],
[0.2036, 0.1659, 0.1662, 0.0000, 0.0000, 0.0000],
[0.1869, 0.1667, 0.1668, 0.1571, 0.0000, 0.0000],
[0.1830, 0.1669, 0.1670, 0.1588, 0.1658, 0.0000],
[0.1935, 0.1663, 0.1666, 0.1542, 0.1666, 0.1529]],
grad_fn=<MulBackward0>The future positions are now 0, but the rows no longer sum to 1: the probability distribution is broken.
Step 4. Renormalize
row_sums          = masked_simple.sum(dim=-1, keepdim=True)
masked_simple_norm = masked_simple / row_sums
tensor([[1.0000, 0.0000, 0.0000, 0.0000, 0.0000, 0.0000],
[0.5517, 0.4483, 0.0000, 0.0000, 0.0000, 0.0000],
[0.3800, 0.3097, 0.3103, 0.0000, 0.0000, 0.0000],
[0.2758, 0.2460, 0.2462, 0.2319, 0.0000, 0.0000],
[0.2175, 0.1983, 0.1984, 0.1888, 0.1971, 0.0000],
[0.1935, 0.1663, 0.1666, 0.1542, 0.1666, 0.1529]],
grad_fn=<DivBackward0>)Each row sums to 1. The masked weights are zero, and the remaining weights are redistributed proportionally.
Note: no information leakage One might worry that the future tokens have already “contaminated” the result through the initial softmax, before being zeroed out. They have not. Renormalizing after masking is mathematically equivalent to having computed the softmax over the unmasked positions only from the start. Future tokens have no influence at all on the final distribution.
Proof
Setup and notation
Consider a sequence of tokens. Each token at position has three vectors, obtained through linear projections of its embedding:
- : query vector
- : key vector
- : value vector
For the current token at position , the raw attention score with each token at position is:
The output of the attention mechanism for token is:
Method 1. Global softmax, then masking and renormalization
Step 1. Softmax over all the tokens.
We compute the attention weights with no restriction:
All the tokens contribute to the denominator, including future ones.
Step 2. Applying the triangular mask.
We zero out the weights corresponding to future tokens:
After this step, the weights no longer sum to 1: some probability mass has been removed.
Step 3. Renormalization.
We divide each weight by the sum of its row:
Explicit expansion. We simplify the numerator and the denominator separately.
For the numerator, we distinguish two cases depending on the position of relative to , applying first the definition of (Step 2) and then that of (Step 1):
For the denominator, we expand by separating the visible positions () from the future ones (), then apply first the definition of (Step 2) and then that of (Step 1):
The term is constant with respect to , so we can factor it out:
We substitute the numerator and denominator into the expression of for :
The factor appears in the numerator and in the denominator, so it cancels out exactly:
Method 2. Masking the raw scores before the softmax
Step 1. Masking the raw scores.
We replace the scores of future tokens with before any computation:
Step 2. A single softmax over the masked scores.
Explicit expansion. We split the denominator into visible and future positions, then apply the definition of :
Likewise for the numerator, applying the definition of :
We therefore get:
Equivalence of the two methods
Comparing the two boxed results term by term is immediate:
We conclude:
This is an exact algebraic equality. In Method 1, the factor introduced by the first softmax cancels out exactly during renormalization. The initial presence of the future tokens in the computation leaves no trace in the final result: the denominator only contains , exactly as in Method 2, where the future tokens were never included. There is therefore no information leakage.
Efficient approach: mask before softmax with −∞
The naive approach applies softmax and then corrects it. We can do better: mask the attention scores before the softmax by replacing the future positions with .
The justification is immediate: , so softmax automatically assigns zero weight to these positions, and the remaining weights sum to 1, with no manual renormalization.
mask   = torch.triu(torch.ones(context_length, context_length), diagonal=1)
masked = attn_scores.masked_fill(mask.bool(), -torch.inf)
torch.triu with diagonal=1 isolates the strictly upper triangle (excluding the diagonal), that is, the future positions. masked_fill replaces these positions with .
tensor([[0.2899,   -inf,   -inf,   -inf,   -inf,   -inf],
        [0.4656, 0.1723,   -inf,   -inf,   -inf,   -inf],
        [0.4594, 0.1703, 0.1731,   -inf,   -inf,   -inf],
        [0.2642, 0.1024, 0.1036, 0.0186,   -inf,   -inf],
        [0.2183, 0.0874, 0.0882, 0.0177, 0.0786,   -inf],
        [0.3408, 0.1270, 0.1290, 0.0198, 0.1290, 0.0078]],
       grad_fn=<MaskedFillBackward0>)
All that remains is to apply softmax:
attn_weights = torch.softmax(masked / keys.shape[-1]**0.5, dim=-1)tensor([[1.0000, 0.0000, 0.0000, 0.0000, 0.0000, 0.0000],
[0.5517, 0.4483, 0.0000, 0.0000, 0.0000, 0.0000],
[0.3800, 0.3097, 0.3103, 0.0000, 0.0000, 0.0000],
[0.2758, 0.2460, 0.2462, 0.2319, 0.0000, 0.0000],
[0.2175, 0.1983, 0.1984, 0.1888, 0.1971, 0.0000],
[0.1935, 0.1663, 0.1666, 0.1542, 0.1666, 0.1529]],
grad_fn=<SoftmaxBackward0>)The result is identical to the naive approach, in two steps instead of four. This is the approach used in practice.
Masking Additional Attention Weights with Dropout
Dropout is a regularization technique proposed by Geoffrey Hinton in 2012. At each training step, each neuron has a probability (the dropout rate) of being temporarily switched off: ignored for this pass, but possibly active in the next one. After training, no neuron is ever switched off.
The intuition behind this technique may seem paradoxical. Imagine a company where every employee flips a coin each morning to decide whether to come to work. The company would be forced to adapt: it could no longer rely on a single person for a critical task, all expertise would have to be spread out, and employees would learn to work with many colleagues rather than a fixed handful. It would become far more robust. This is exactly what happens in a neural network: neurons trained under dropout cannot co-adapt with their usual neighbors; each one becomes more useful on its own and less sensitive to small variations in the input.
Another way to look at it: at each training step, the active network is different (one of possible configurations for neurons). The final network can be seen as an average ensemble of all these subnetworks.
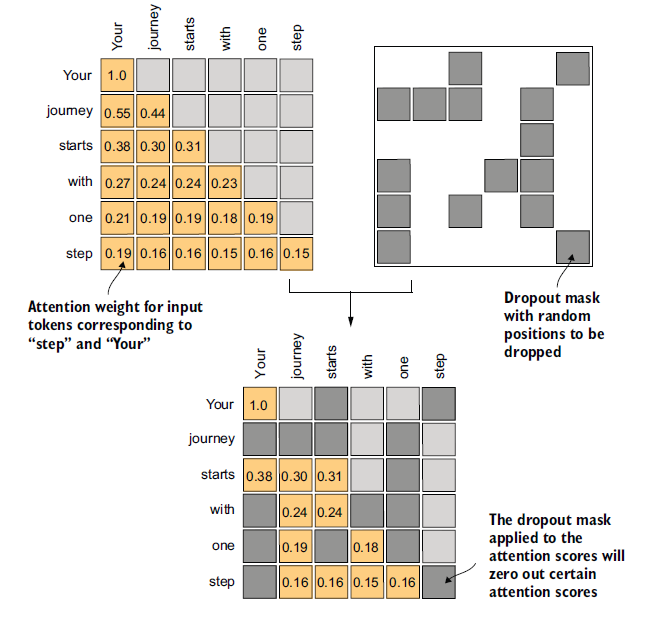
In the attention mechanism, dropout is applied directly to the attention weights, which is the most common variant in practice. Concretely, the causal mask and the dropout mask are layered on top of each other: the first zeroes out the upper triangle (future tokens), the second randomly zeroes out additional positions among the visible tokens.
Automatic rescaling
With a dropout rate , the surviving weights are multiplied by . This correction is necessary: during training, a neuron is connected on average to only a fraction of its usual inputs. Without this compensation, at inference time (when all neurons are active) the neuron would receive a signal with a very different magnitude from what it learned.
We check this behavior on a matrix of 1s with :
torch.manual_seed(123)
dropout = torch.nn.Dropout(0.5)
example = torch.ones(6, 6)
print(dropout(example))
tensor([[2., 2., 0., 2., 2., 0.],
[0., 0., 0., 2., 0., 2.],
[2., 2., 2., 2., 0., 2.],
[0., 2., 2., 0., 0., 2.],
[0., 2., 0., 2., 0., 2.],
[0., 2., 2., 2., 2., 0.]])The elements that remain nonzero after dropout equal , which confirms the rescaling.
Applying it to the causal attention weights
torch.manual_seed(123)
print(dropout(attn_weights))
tensor([[2.0000, 0.0000, 0.0000, 0.0000, 0.0000, 0.0000],
[0.0000, 0.0000, 0.0000, 0.0000, 0.0000, 0.0000],
[0.7599, 0.6194, 0.6206, 0.0000, 0.0000, 0.0000],
[0.0000, 0.4921, 0.4925, 0.0000, 0.0000, 0.0000],
[0.0000, 0.3966, 0.0000, 0.3775, 0.0000, 0.0000],
[0.0000, 0.3327, 0.3331, 0.3084, 0.3331, 0.0000]],
grad_fn=<MulBackward0>)The causal mask (zeroed upper triangle) is preserved. Dropout is layered on top of it, randomly zeroing out additional weights among the visible positions and rescaling the survivors.
Note: dropout results can vary depending on the operating system, regardless of
manual_seed. This behavior is documented in the PyTorch issue tracker.
Implementing a Compact Causal Attention Class
We now integrate the causal mask and dropout into a CausalAttention class that replaces SelfAttention. This class must also handle batched inputs, that is, several sequences processed in parallel.
To simulate a batch, we duplicate the input:
batch = torch.stack((inputs, inputs), dim=0)
print(batch.shape)
# torch.Size([2, 6, 3])
A 3D tensor of shape (batch_size, num_tokens, d_in): 2 sequences, 6 tokens each, 3-dimensional embeddings.
The code
class CausalAttention(nn.Module):

    def __init__(self, d_in, d_out, context_length, dropout, qkv_bias=False):
        super().__init__()
        self.d_out = d_out
        self.W_query = nn.Linear(d_in, d_out, bias=qkv_bias)
        self.W_key   = nn.Linear(d_in, d_out, bias=qkv_bias)
        self.W_value = nn.Linear(d_in, d_out, bias=qkv_bias)
        self.dropout = nn.Dropout(dropout)
        self.register_buffer(
            'mask',
            torch.triu(torch.ones(context_length, context_length), diagonal=1)
        )

    def forward(self, x):
        b, num_tokens, d_in = x.shape
        keys    = self.W_key(x)
        queries = self.W_query(x)
        values  = self.W_value(x)

        attn_scores = queries @ keys.transpose(1, 2)
        attn_scores.masked_fill_(
            self.mask.bool()[:num_tokens, :num_tokens], -torch.inf
        )
        attn_weights = torch.softmax(attn_scores / keys.shape[-1]**0.5, dim=-1)
        attn_weights = self.dropout(attn_weights)

        context_vec = attn_weights @ values
return context_vectorch.manual_seed(123)
context_length = batch.shape[1]
ca = CausalAttention(d_in, d_out, context_length, 0.0)
context_vecs = ca(batch)
print("context_vecs.shape:", context_vecs.shape)
# context_vecs.shape: torch.Size([2, 6, 2])Point 1. register_buffer: what is it and why?
In a PyTorch nn.Module, there are two kinds of tensors:
Parameters (nn.Parameter): the learned weights, registered through nn.Linear. PyTorch tracks them automatically: they appear in model.parameters(), receive gradients, and are moved to the GPU with model.to(device).
Buffers (register_buffer): fixed, non-learned tensors that the model needs but that must not be updated by the optimizer. This is exactly the case of the causal mask: it is constant, computed once at initialization.
Without register_buffer, we could simply write self.mask = torch.triu(...). It would work locally, but with two problems:
The mask would not be moved to the GPU automatically. If we call model.to("cuda"), the weights move, but self.mask does not. At the masked_fill_ call, PyTorch would raise a device mismatch error: the mask is on the CPU and the attention scores are on the GPU.
The mask would not appear in model.state_dict(), the dictionary that captures the model’s full state for saving. A model reloaded from a checkpoint would lose its mask.
register_buffer solves both: the mask follows the model everywhere (CPU/GPU) and is included in state_dict().
Point 2. Anatomy of the masking code
register_buffer('mask', torch.triu(...))
The call register_buffer('mask', tensor) does two things: it registers the tensor as a buffer of the module, and it makes it accessible as self.mask. The first argument, 'mask', is simply the name under which the buffer is registered: that name becomes the attribute. We could have written register_buffer('causal_mask', ...) and then accessed it as self.causal_mask.
The registered tensor is:
torch.triu(torch.ones(context_length, context_length), diagonal=1)torch.triu extracts the upper triangle of a matrix. With diagonal=1, the main diagonal is excluded: only the positions strictly above it are 1:
Mask with diagonal=1:
 tensor([[0., 1., 1., 1., 1., 1.],
        [0., 0., 1., 1., 1., 1.],
        [0., 0., 0., 1., 1., 1.],
        [0., 0., 0., 0., 1., 1.],
        [0., 0., 0., 0., 0., 1.],
        [0., 0., 0., 0., 0., 0.]])
The 1s mark exactly the future positions to mask.
attn_scores.masked_fill_(self.mask.bool()[:num_tokens, :num_tokens], -torch.inf)
Let’s go through it argument by argument.
self.mask.bool() converts the mask from float (0.0 / 1.0) to bool (False / True). masked_fill_ expects a boolean mask: the positions set to True will be replaced.
[:num_tokens, :num_tokens]: the mask was created at initialization with the maximum size context_length × context_length. The current sequence may be shorter. This slicing extracts the submask with the exact size of the sequence being processed, without recreating the tensor on every call.
-torch.inf is the replacement value for the future positions. Since , softmax will give them zero weight.
masked_fill_ (with an underscore) is an in-place operation: attn_scores is modified directly in memory with no intermediate copy, which saves memory for potentially large attention matrices.
In short: for each position where self.mask[i,j] is True (that is, , a future token), the corresponding value in attn_scores is replaced with .
Point 3. keys.transpose(1, 2) instead of keys.T
In SelfAttention_v1 and SelfAttention_v2, we had keys.T because the inputs were 2D, (num_tokens, d_out). Here keys is 3D: (b, num_tokens, d_out). .T would reverse all the axes, giving (d_out, num_tokens, b), which is wrong. .transpose(1, 2) only swaps the last two dimensions, giving (b, d_out, num_tokens): the batch dimension stays in position 0, and the matrix product works correctly on each sequence of the batch independently.
Extending Single-Head Attention to Multi-Head Attention
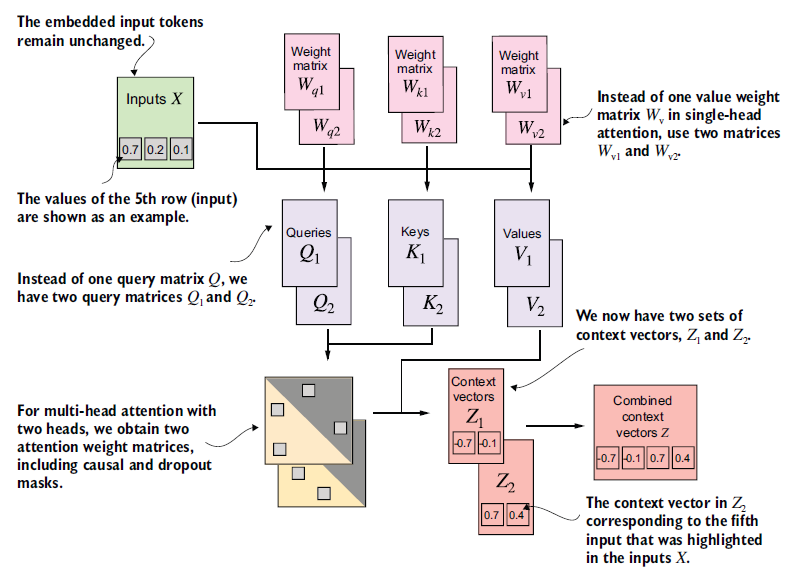
Multi-head attention runs the attention mechanism several times in parallel, each with its own weight matrices , , . Each head learns to specialize in a different kind of relationship within the sequence. A single CausalAttention module corresponds to single-head attention: one set of weights processing the input.
Stacking Several Single-Head Attention Layers
The idea
The most direct way to implement multi-head attention is to create several independent CausalAttention modules, run them on the same input, and concatenate their outputs.
Implementation
class MultiHeadAttentionWrapper(nn.Module):

    def __init__(self, d_in, d_out, context_length,
                 dropout, num_heads, qkv_bias=False):
        super().__init__()
        self.heads = nn.ModuleList(
            [CausalAttention(d_in, d_out, context_length, dropout, qkv_bias)
             for _ in range(num_heads)]
        )

    def forward(self, x):
        return torch.cat([head(x) for head in self.heads], dim=-1)
Two points deserve attention.
nn.ModuleList is a list of CausalAttention modules whose parameters are managed centrally by MultiHeadAttentionWrapper: they are accessible through model.parameters(), moved with model.to(device), and saved in state_dict().
torch.cat(..., dim=-1) concatenates the outputs of each head along the last dimension, that is, the embedding dimension. If each head produces vectors of dimension d_out, the final output has dimension d_out × num_heads.
Example
torch.manual_seed(123)
context_length = batch.shape[1]
mha = MultiHeadAttentionWrapper(d_in, d_out, context_length, 0.0, num_heads=2)
context_vecs = mha(batch)
print(context_vecs)
print("context_vecs.shape:", context_vecs.shape)
tensor([[[-0.4519, 0.2216, 0.4772, 0.1063],
[-0.5874, 0.0058, 0.5891, 0.3257],
[-0.6300, -0.0632, 0.6202, 0.3860],
[-0.5675, -0.0843, 0.5478, 0.3589],
[-0.5526, -0.0981, 0.5321, 0.3428],
[-0.5299, -0.1081, 0.5077, 0.3493]],
[[-0.4519, 0.2216, 0.4772, 0.1063],
[-0.5874, 0.0058, 0.5891, 0.3257],
[-0.6300, -0.0632, 0.6202, 0.3860],
[-0.5675, -0.0843, 0.5478, 0.3589],
[-0.5526, -0.0981, 0.5321, 0.3428],
[-0.5299, -0.1081, 0.5077, 0.3493]]], grad_fn=<CatBackward0>)
context_vecs.shape torch.Size([2, 6, 4])The shape (2, 6, 4) reads as: 2 sequences in the batch, 6 tokens each, context vectors of dimension . The two sequences are identical (the batch was simulated by duplication), hence the identical context vectors.
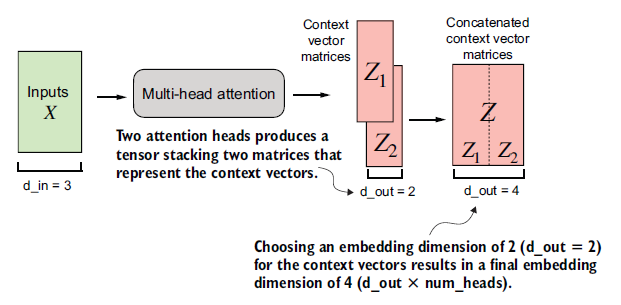
num_heads=2 and d_out=2, each head produces a matrix of 2-dimensional context vectors. The two matrices are concatenated along the column dimension, giving a final dimension of . Source: Raschka (2024).Exercise 3.2: Reducing the dimension of the context vectors
Change the arguments of
MultiHeadAttentionWrapper(..., num_heads=2)so that the output context vectors have dimension 2 instead of 4, while keepingnum_heads=2.
Solution:
The output dimension is d_out × num_heads. So we simply pass d_out=1: each head produces 1-dimensional vectors, and their concatenation gives dimension 2.
torch.manual_seed(123)
mha = MultiHeadAttentionWrapper(d_in, 1, context_length, 0.0, num_heads=2)
print(mha(batch).shape)
torch.Size([2, 6, 2])Limitation of this approach
The heads are processed sequentially in forward through [head(x) for head in self.heads]. This is functionally correct but inefficient: we make num_heads separate passes where a single matrix operation could compute everything in parallel. The next section presents an implementation that takes advantage of this parallelism.
Implementing Multi-Head Attention with Weight Splits
The MultiHeadAttention class merges MultiHeadAttentionWrapper and
CausalAttention into a single unit. The guiding idea: perform a single
linear projection of dimension , then implicitly split the result
into subspaces of dimension .
Unlike MultiHeadAttentionWrapper, which kept weight matrices
and repeated the matrix multiplication
for each head, a single multiplication is enough here.
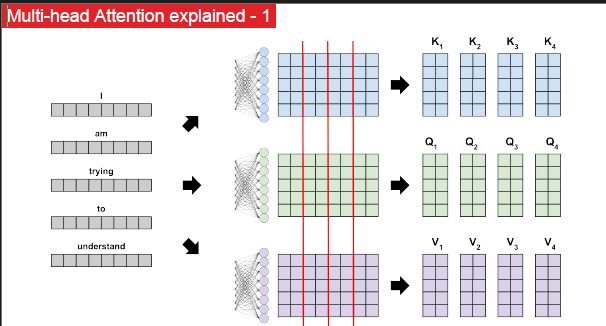
Below, we describe the successive transformations applied to the key tensor (the same ones apply identically to and ).
Step 1. Single projection: (b, num_tokens, d_in) → (b, num_tokens, d_out)
keys = self.W_key(x) # (b, num_tokens, d_out)Each row of the output tensor is the key vector of token .
Step 2. Splitting by head with .view(): (b, num_tokens, d_out) → (b, num_tokens, H, d_h)
keys = keys.view(b, num_tokens, self.num_heads, self.head_dim)What .view() actually does
To understand .view(), you first need to understand how PyTorch stores data.
Memory is a hallway of numbered slots. When PyTorch creates a tensor, it reserves a block of consecutive slots in memory (RAM), one slot per number. For example, a matrix
is stored in memory as a simple row of 6 slots:
PyTorch just remembers two pieces of information separately: (1) the address of the first slot, and (2) the shape (2, 3), which lets it compute where to find each element: the element in row , column is in slot .
.view() changes the reading grid, not where the data physically sits. Calling .view(3, 2) on the same memory amounts to deciding to read it as
PyTorch simply updates the shape from (2, 3) to (3, 2) and recomputes the access formula: element is now in slot . That’s all.
This is why .view() is called copy-free: it allocates no new memory and moves no numbers. It costs almost nothing in time or memory, whatever the size of the tensor.
Applying it to our keys
Notation. For a token and a head , let be the associated key subvector.
After step 1, for a fixed token , the vector holds the projections of all the heads laid end to end:
.view(b, num_tokens, H, d_h) tells PyTorch: “reinterpret the dimension
as two nested dimensions”. Without moving anything
in memory, the same token is now accessible as an
block:
The -th row of this block is exactly , the key vector of token for head .
.view() reinterprets the dimension as .
For each token , the vector becomes
a block whose -th row
is . No data is moved in memory.Step 3. Reorganizing by head with .transpose(1, 2): (b, num_tokens, H, d_h) → (b, H, num_tokens, d_h)
keys = keys.transpose(1, 2)Notation. Let
be the key matrix of head over the whole sequence, that is, all the projections into the same subspace, one row per token.
What .transpose() actually does, and why it differs from .view()
Like .view(), .transpose() moves nothing in memory: it just changes the access formula. But it creates a problem that .view() did not.
Let’s go back to the matrix:
Physical memory:
With .view(3, 2), PyTorch reread these same slots as “3 rows of 2 columns”, and each consecutive row really was side by side in memory. No problem.
That is:
With .transpose(), we logically get:
To read the first row of (the elements and ), PyTorch has to skip slots: it takes slot 0 (1), then slot 3 (4). In between are slots 1 and 2, which logically belong to other rows. The logical order and the memory order diverge:
A tensor is non-contiguous when reading its elements in logical order requires skipping slots in memory.
The two representations of the key tensor
Left representation: organized by token.
In the (b, num_tokens, H, d_h) shape produced by .view(), the main
iteration dimension is the token. For a fixed token , the block
gathers the projections of all the heads for that token:
We read the tensor head by head for a given token. In memory, the data is laid out in this order: all the heads of token 1, then all the heads of token 2, and so on. The matrices exist conceptually, but their rows are interleaved: followed by , then followed by , and so on. To rebuild , you would have to skip slots on every row.
Right representation: organized by head.
After .transpose(1, 2), the shape is (b, H, num_tokens, d_h). For a fixed head ,
the block gathers the projections of all the
tokens for that head:
We read the tensor token by token for a given head. Each forms
an independent logical block. But as seen above, .transpose() has not
moved the data: the logical order and the memory order still diverge. The
tensor is non-contiguous.
Transposing does not change the data, only the way it is traversed: we switch from reading by token to reading by head.
.transpose(1, 2) swaps the num_tokens and num_heads dimensions.
On the left, the block gathers all the heads of a given token.
On the right, the block gathers all the tokens of a given head.
Physical memory does not move: only the reading order changes.Step 4. Attention scores through batched multiplication
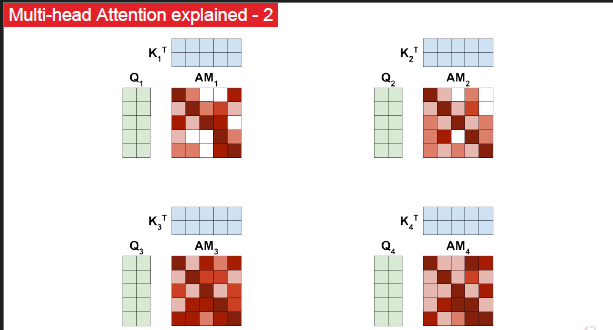
Since , , all have shape , the product
attn_scores = queries @ keys.transpose(2, 3)computes for all the heads and all the batch elements at once:
Step 5. Recombining the heads
After causal masking, softmax and dropout, the context vectors are recombined:
context_vec = (attn_weights @ values).transpose(1, 2)
# (b, H, T, d_h) → (b, T, H, d_h)
context_vec = context_vec.contiguous().view(b, num_tokens, self.d_out)
# (b, T, H, d_h) → (b, T, d_out)
What .contiguous() actually does
.transpose() left the tensor in a state where the logical order and the memory order
diverge. .view() cannot handle this gap: it always assumes that reading
the elements in logical order means reading them slot after slot in memory.
Calling .view() directly would therefore raise an error.
.contiguous() solves this: it allocates a new memory block and copies
the data into it in the order that matches the current logical shape.
With our numerical example: after .transpose(), the tensor is logically
but the memory still holds :
.contiguous() creates a new block where the two orders match:
.view() can then be applied safely.
In short.
.view()and.transpose()are both copy-free: they only change how PyTorch reads memory. But.transpose()creates a gap between logical order and memory order that.view()cannot handle..contiguous()is the explicit copy that reconciles them.
The .view(b, num_tokens, self.d_out) that follows concatenates the outputs of the heads
for each token:
Finally, a linear projection mixes the information from the different heads:
context_vec = self.out_proj(context_vec)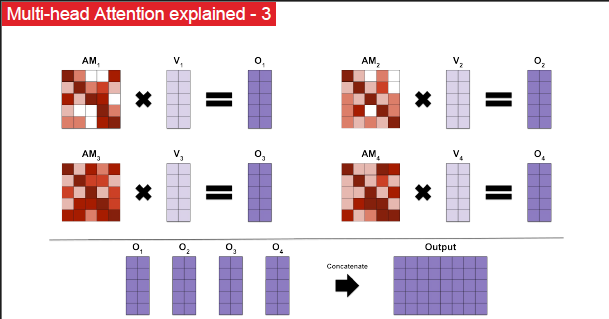
The complete code
The five steps, brought together in a single class:
class MultiHeadAttention(nn.Module):
    def __init__(self, d_in, d_out, context_length, dropout, num_heads, qkv_bias=False):
        super().__init__()
        assert d_out % num_heads == 0, "d_out must be divisible by num_heads"

        self.d_out = d_out
        self.num_heads = num_heads
        self.head_dim = d_out // num_heads  # dimension of each head

        self.W_query = nn.Linear(d_in, d_out, bias=qkv_bias)
        self.W_key   = nn.Linear(d_in, d_out, bias=qkv_bias)
        self.W_value = nn.Linear(d_in, d_out, bias=qkv_bias)
        self.out_proj = nn.Linear(d_out, d_out)  # final projection that mixes the heads
        self.dropout = nn.Dropout(dropout)
        self.register_buffer(
            "mask",
            torch.triu(torch.ones(context_length, context_length), diagonal=1)
        )

    def forward(self, x):
        b, num_tokens, d_in = x.shape

        # Step 1: a single projection for all the heads
        keys    = self.W_key(x)
        queries = self.W_query(x)
        values  = self.W_value(x)

        # Step 2: split by head
        keys    = keys.view(b, num_tokens, self.num_heads, self.head_dim)
        queries = queries.view(b, num_tokens, self.num_heads, self.head_dim)
        values  = values.view(b, num_tokens, self.num_heads, self.head_dim)

        # Step 3: (b, H, T, d_h), one matrix per head
        keys    = keys.transpose(1, 2)
        queries = queries.transpose(1, 2)
        values  = values.transpose(1, 2)

        # Step 4: scores, causal mask, softmax and dropout, for all heads at once
        attn_scores = queries @ keys.transpose(2, 3)
        mask_bool = self.mask.bool()[:num_tokens, :num_tokens]
        attn_scores.masked_fill_(mask_bool, -torch.inf)
        attn_weights = torch.softmax(attn_scores / keys.shape[-1]**0.5, dim=-1)
        attn_weights = self.dropout(attn_weights)

        # Step 5: recombine the heads, then the final projection
        context_vec = (attn_weights @ values).transpose(1, 2)
        context_vec = context_vec.contiguous().view(b, num_tokens, self.d_out)
return self.out_proj(context_vec)torch.manual_seed(123)
batch_size, context_length, d_in = batch.shape
mha = MultiHeadAttention(d_in, d_out=2, context_length=context_length, dropout=0.0, num_heads=2)
context_vecs = mha(batch)
print("context_vecs.shape:", context_vecs.shape)context_vecs.shape: torch.Size([2, 6, 2])Unlike MultiHeadAttentionWrapper, where d_out was the dimension of each head, d_out here is the dimension of the total output: with d_out=2 and num_heads=2, each head works in dimension 1. This is the convention GPT models use.
Exercise 3.3: Initializing a GPT-2-sized attention module
Using the
MultiHeadAttentionclass, initialize a multi-head attention module with the same number of heads as the smallest GPT-2 model (12 heads). Also use GPT-2’s input and output embedding dimensions (768). The smallest GPT-2 supports a context length of 1,024 tokens.
Solution:
# Parameters of the smallest GPT-2
d_in = 768              # input embedding dimension
d_out = 768             # output dimension (same as d_in in GPT-2)
num_heads = 12          # number of attention heads
context_length = 1024   # maximum context length

mha = MultiHeadAttention(
    d_in=d_in,
    d_out=d_out,
    context_length=context_length,
    dropout=0.1,
    num_heads=num_heads,
    qkv_bias=False
)

print("Dimension per head:", mha.head_dim)
print("Number of parameters:", sum(p.numel() for p in mha.parameters()))
Dimension per head: 64
Number of parameters: 2360064Each head works in dimension . The three projections , , hold weights, and the output projection (weights and bias), for a total of 2,360,064 parameters.
Summary
The key points of this chapter on attention and multi-head attention:
Attention fundamentals
- Attention mechanisms turn a set of inputs into enriched context representations that incorporate information from every token.
- Simple attention is a weighted sum: each output element is a linear combination of the inputs, with weights learned by the model.
- The attention weights are computed through dot products between queries and keys, a compact and efficient formulation.
Dot-product attention
- We introduce three trainable linear projections: queries (), keys (), and values (), which let the model learn what kinds of relationships to look for and how to use them.
- The raw score is normalized by the square root of the dimension (scaling) to keep the variance from exploding.
- Softmax turns these scores into probabilistic weights that sum to 1 per row.
Causal attention
- For language models that read and generate from left to right, we apply a causal mask that prevents each token from accessing future tokens.
- Two equivalent approaches: (1) apply softmax, then mask and renormalize, or (2) replace the future scores with before softmax; the second is more efficient in practice.
- Dropout applied to the attention weights makes the model more robust by forcing it not to over-rely on individual connections.
Multi-head attention
- A single attention head captures a single way of combining tokens. Several heads running in parallel let the model explore several subspaces and relationships at once.
- The naive implementation (stacking single-head modules) is conceptually simple but inefficient: the matrix multiplication (the most expensive operation) is repeated times.
- The efficient implementation (the
MultiHeadAttentionclass) performs a single projection of dimension , then splits and reorganizes it with.view()and.transpose()without copying the data. The resulting matrix operations (a batched product over all the heads) take advantage of GPU vectorization.
Tensor operations and memory management
.view()and.transpose()are copy-free operations: they only change how PyTorch accesses memory..transpose()creates a divergence between logical order and memory order, which makes it impossible to apply.view()directly afterwards..contiguous()resolves this gap by reallocating and rewriting the data so that the two orders match, a necessary step before.view().
Real-world scale: GPT-2
- The smallest GPT-2 (117M parameters) has 12 heads, an embedding dimension of 768 and a context length of 1,024. Each head operates in dimension 64.
- Modern LLM architectures (GPT-3, LLaMA, etc.) increase the number of heads (up to 96 for the largest GPT-3) and the dimensions (up to 12,288), but the fundamental design stays the same.
Useful Links
-
Understanding buffers: exploring buffers in attention mechanisms
-
MHA implementations: practical implementations of multi-head attention
Weekly Notes
Every Sunday, I share what I've been learning: papers, ideas, experiments, and questions that stayed with me.
You can unsubscribe at any time with a single click.
Discussion about this post0
Join the discussion
A secure sign-in link will be sent to your email address.
Loading discussion...